About Me
Tagline. Algorithm–system co-design for long-context and efficient architectures.
I am an Algorithm Engineer / Research Scientist at Ant Group working on foundation models. My work lies at the intersection of algorithm design and ML systems, with a focus on making long-context models both scalable and servable in real-world deployments.
I am particularly interested in breaking the (O(N^2)) memory and compute wall of Transformers using theoretically grounded mechanisms and hardware-aware implementations. Recently I have been exploring PDE-inspired token-mixing dynamics and building evidence-first pipelines—profiling, benchmarks, and serving-style experiments—on top of stacks such as Triton and vLLM.
I received my M.S. in Computer Science from Fudan University, advised by Prof. Yu-Gang Jiang (IEEE Fellow) and Prof. Jingjing Chen, where I was part of the Fudan Vision and Learning Laboratory (FVL). Before that, I obtained my B.Eng. in Civil Engineering from Tongji University.
Research Interests
- Long-context & reasoning: inference-time scaling, KV-cache behavior, long-prefill optimization
- Efficient architectures: PDE-driven dynamics, linear/structured attention, state-space style operators
- Algorithm–system co-design: fused kernels, profiling, serving-oriented evaluation
If you are interested in collaborations on long-context efficiency or system-aware evaluation, feel free to reach out at alancurry1456@gmail.com.
🔥 News
- [Feb 2026] New preprint: How Vision Becomes Language: A Layer-wise Information-Theoretic Analysis of Multimodal Reasoning. [arXiv]
- [Nov 2025] Continuous-Time Attention accepted to EMNLP 2025 (Main). [PDF]
- [Sep 2025] Preprint: Where to Add PDE Diffusion in Transformers. [arXiv]
- [Aug 2024] Preprint: Understanding Transformer Architecture through Continuous Dynamics: A Partial Differential Equation Perspective. [arXiv]
📝 Publications
A full publication list is available on [Google Scholar] [Semantic Scholar]
(*: equal contribution; †: project leader)
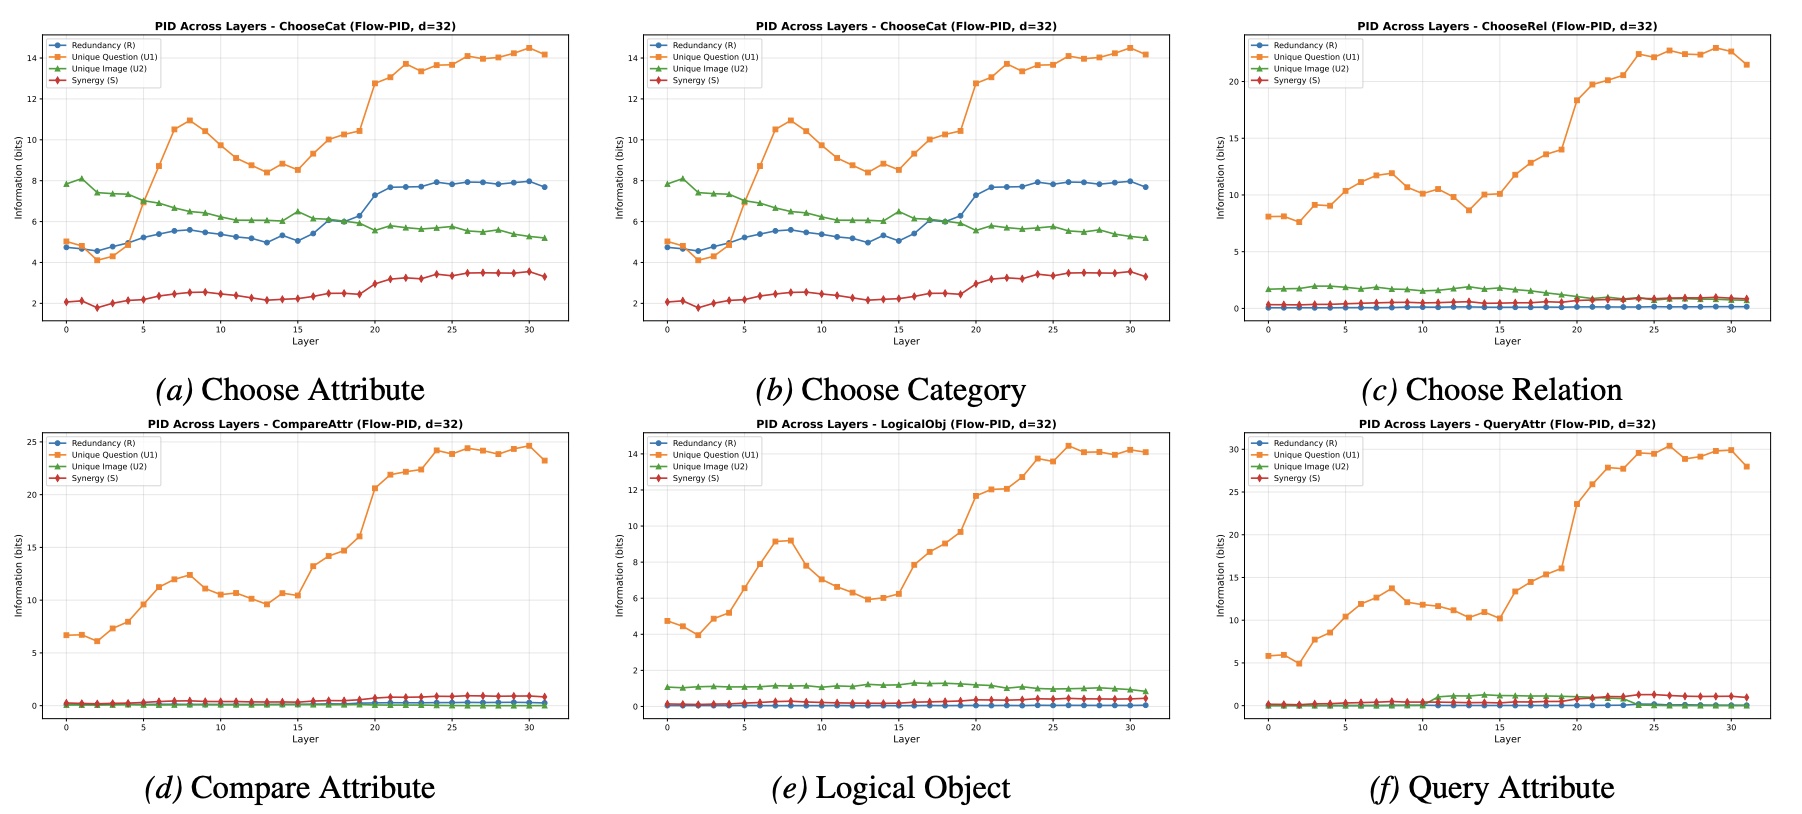

Hongxuan Wu, Yukun Zhang, Xueqing Zhou
arXiv preprint, 2026
[Paper]
TL;DR: A layer-wise PID framework + causal attention knockouts that quantify “vision → language” transduction across depth, turning mechanistic analysis into a practical diagnostic tool for architecture and inference-time interventions.
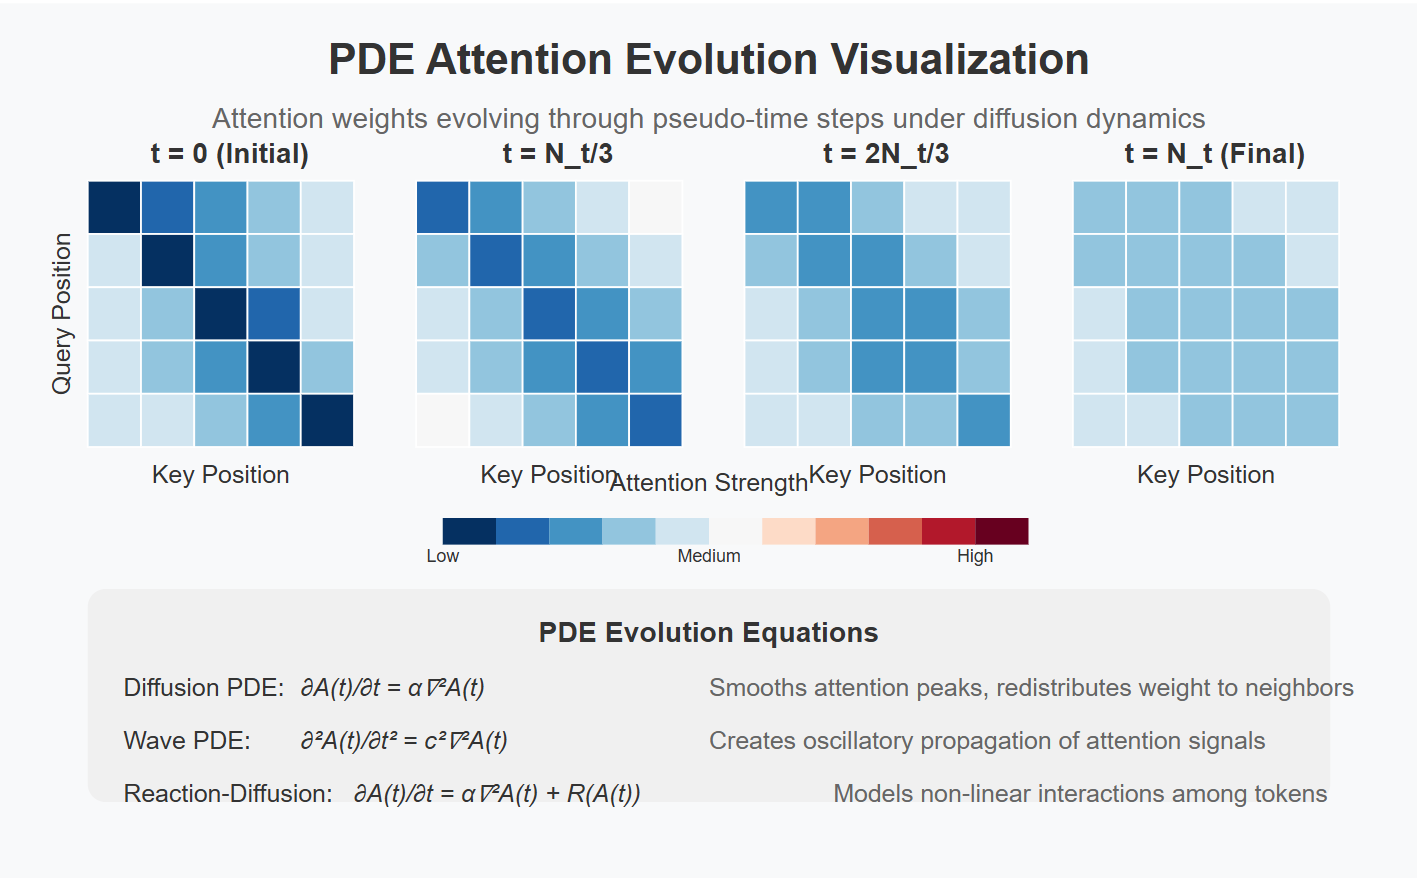

Yukun Zhang*, Xueqing Zhou*
EMNLP, 2025 (Main)
[Paper][Project][Code]
TL;DR: Reimagines attention as a continuous-time PDE evolution for long sequences; emphasizes algorithm–system co-design via kernel/serving-friendly operators and evidence-first evaluation for long-context efficiency.
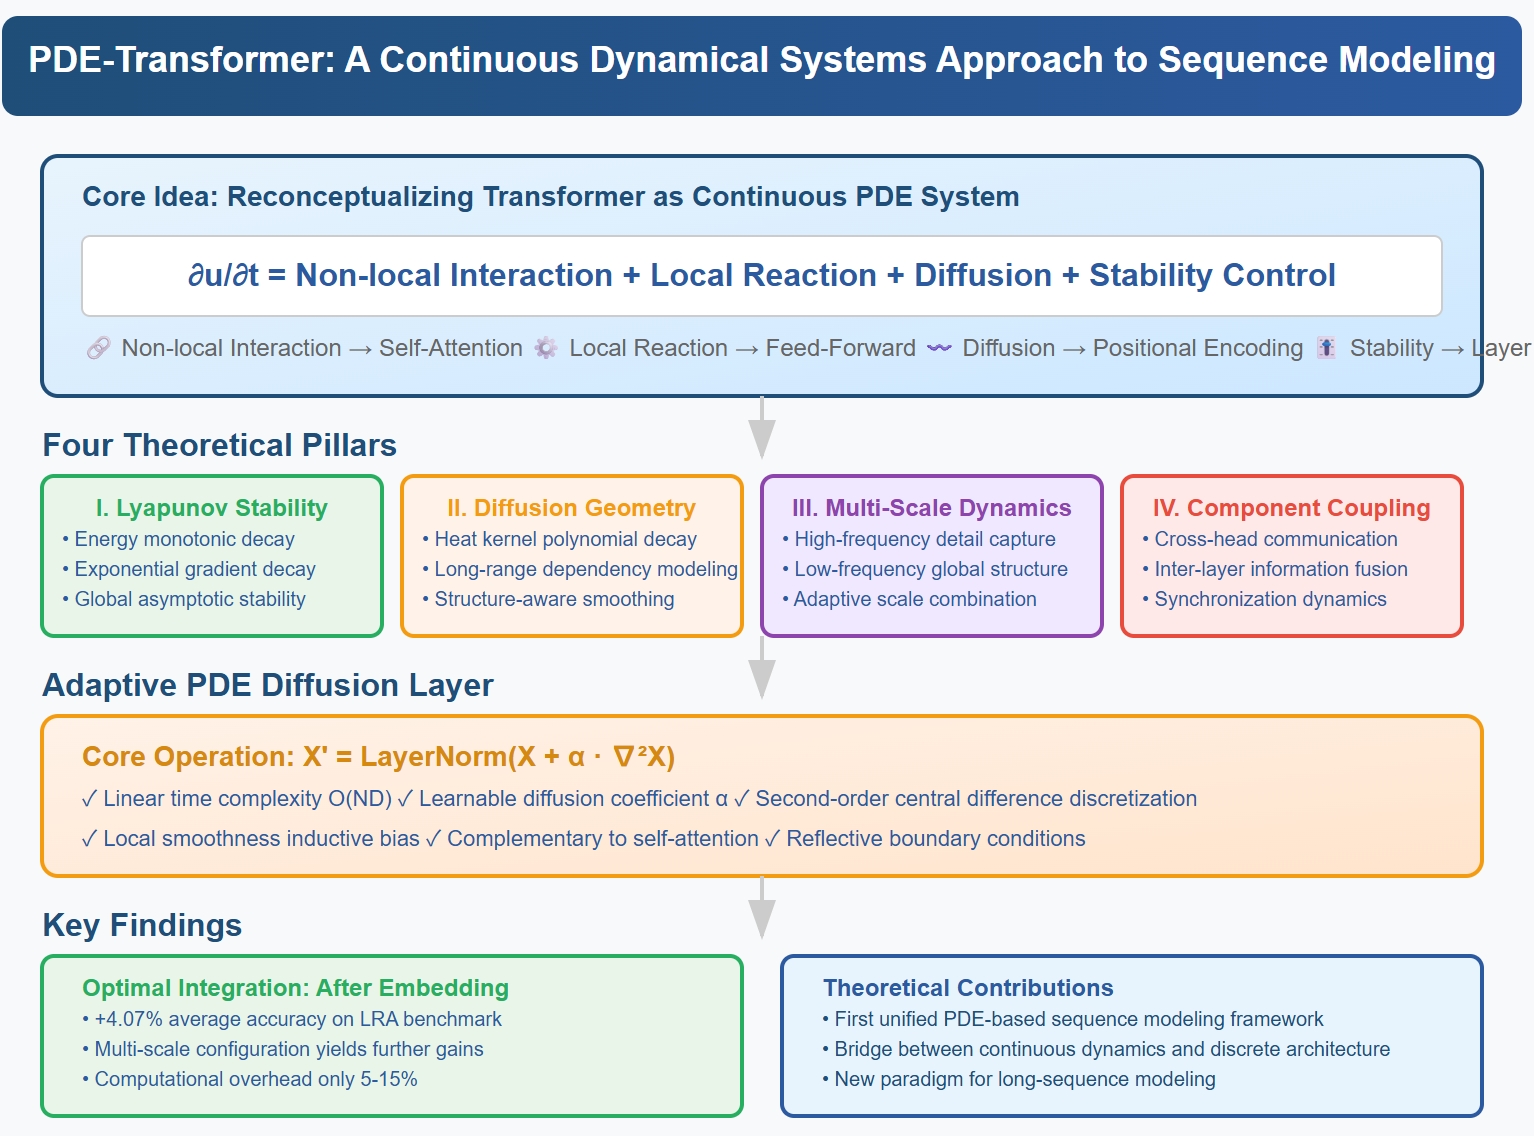

Yukun Zhang*, Xueqing Zhou*
arXiv preprint, 2025
[Paper]
TL;DR: Shows diffusion and attention generally do not commute—placement matters; provides a principled template for composing local-global modules, guiding efficient-architecture design choices under long-sequence constraints.
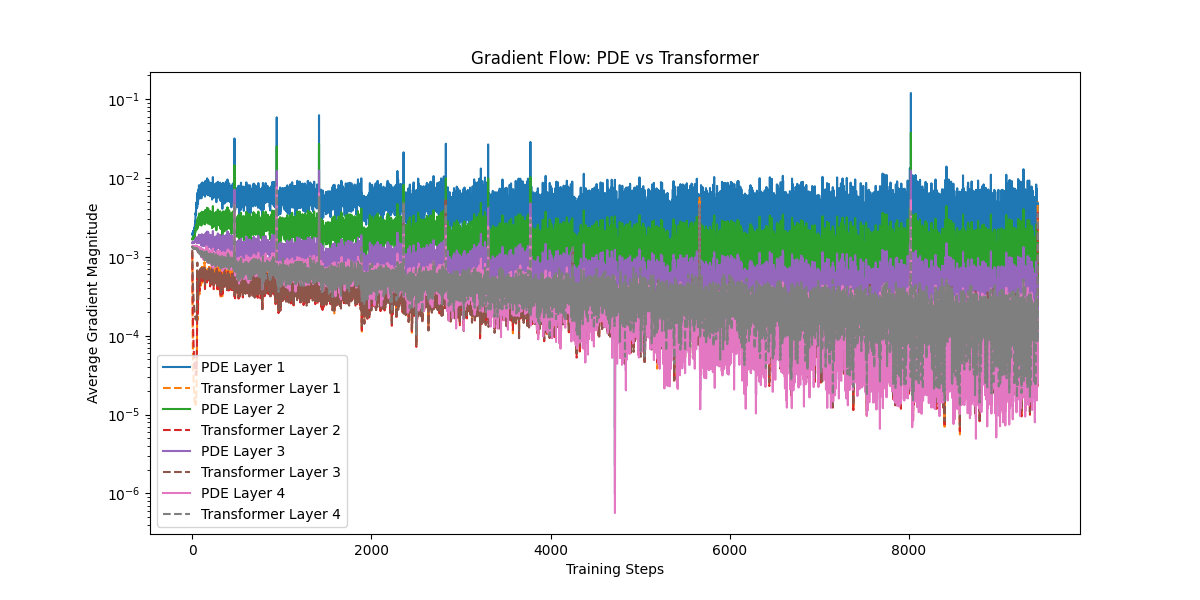

Yukun Zhang*, Xueqing Zhou*
arXiv preprint, 2024
[Paper]
TL;DR: A PDE lens that turns Transformer components into interpretable operators, explaining why stabilizers like residual connections and layer norm are essential—useful for reasoning about stability/efficiency trade-offs in deep architectures.